Centralized vs. Distributed Databases: Which Approach Works Better for eCommerce?
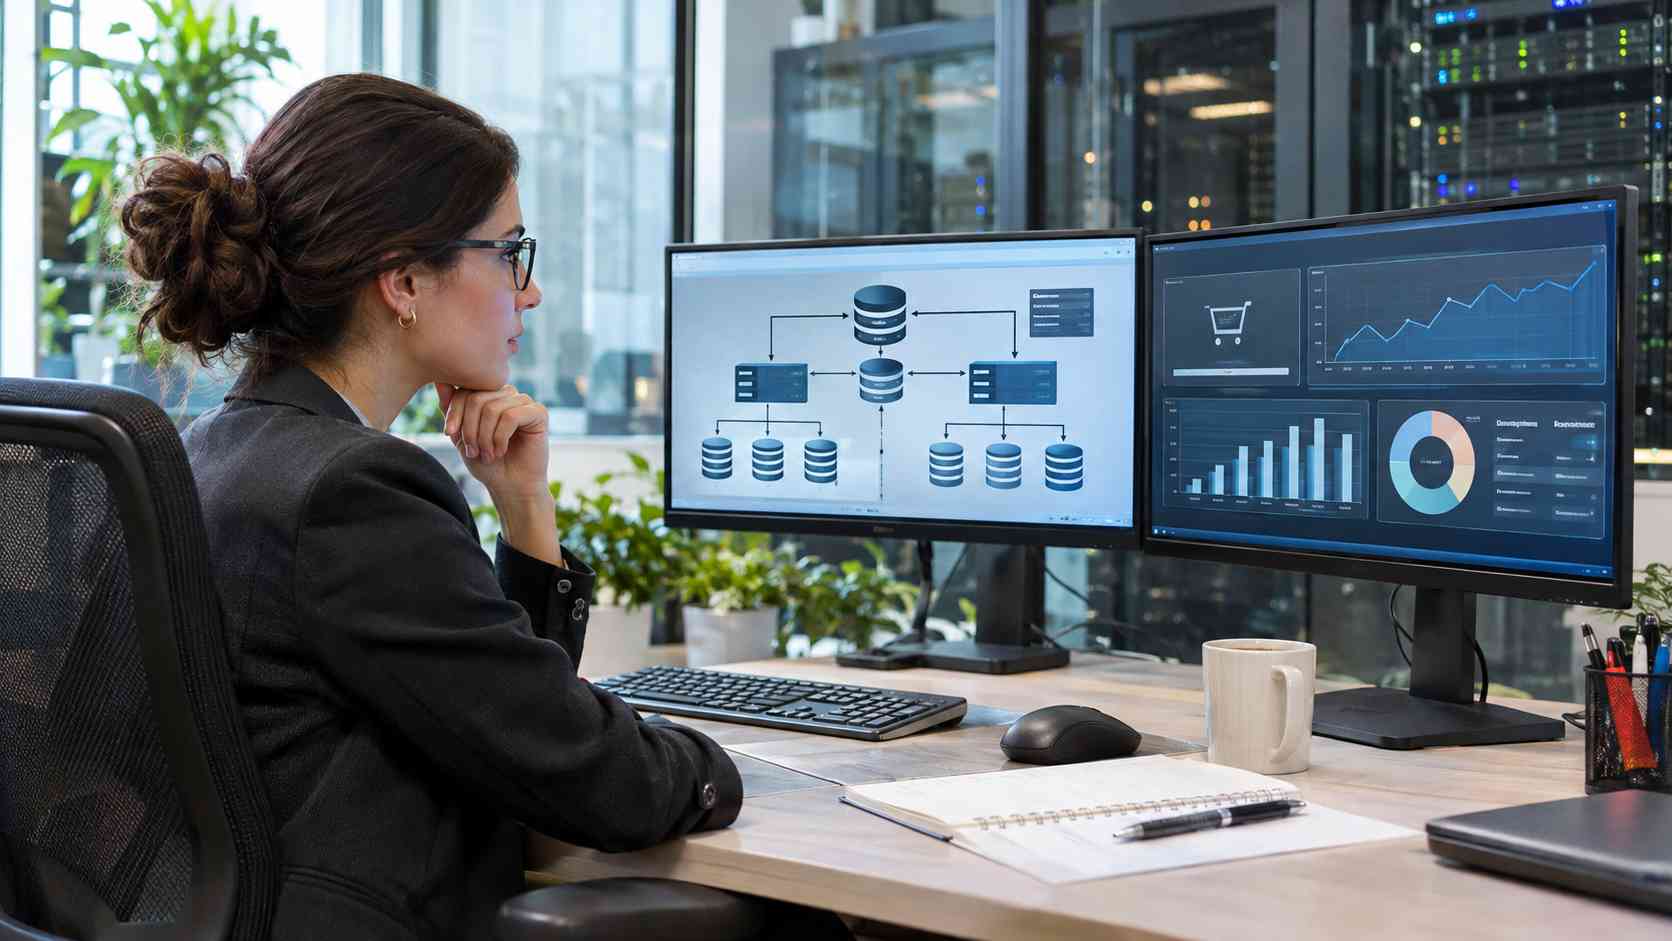
Database Administrator Reviewing eCommerce Infrastructure

Database architecture influences how efficiently eCommerce businesses manage product catalogs, customer accounts, inventory records, and transactions. As online stores expand, their databases must handle increasing amounts of information without compromising accuracy or performance. Choosing between centralized and distributed systems can affect operational costs, reliability, and future growth.

Companies also need databases that connect smoothly with other business applications. Development providers such as Brainvire offer Magento integration and data migration services for these requirements. However, choosing the appropriate database structure involves examining technical needs, business priorities, and available resources rather than relying on a particular service provider.

Understanding Centralized Database Architecture

A centralized database stores and manages information through a primary database system. Applications and authorized users access shared records through this central environment.

This approach simplifies administration because information is managed within one logical system. Product updates, customer details, and transaction records can follow consistent rules.

PostgreSQL documentation describes transaction mechanisms that help preserve data integrity. These capabilities are particularly valuable when businesses process orders, update inventory, and maintain financial records.

Centralized databases also make monitoring, access management, and routine maintenance relatively straightforward.

However, their performance depends on infrastructure capacity. Heavy workloads can create bottlenecks, while inadequate redundancy increases the consequences of system failures.

Understanding Distributed Database Architecture

Distributed databases store or process information across multiple connected servers. These servers may operate within one data center or across different geographic regions.

The main advantage is the ability to distribute workloads. Businesses can add computing resources, improve regional access, and design systems that continue operating during certain infrastructure failures.

Amazon Web Services (AWS) explains that distributed databases can support horizontal scaling by spreading data and processing responsibilities across multiple nodes.

However, coordination becomes more complicated when information exists in several locations. Changes must be synchronized, and network delays can influence when updated records become available.

Distributed systems therefore require careful planning around data consistency, recovery procedures, and communication between servers.

Centralized vs. Distributed Databases: Key Differences

Which Approach Handles Growth More Effectively?

Centralized databases commonly scale by increasing server resources, although replication, partitioning, and other techniques can extend their capacity.

Distributed systems can spread workloads across additional machines. This may benefit large marketplaces experiencing heavy traffic or operating across several regions.

Neither approach guarantees better performance without suitable configuration.

Simpler Maintenance vs. Greater Flexibility

Centralized environments usually require fewer components to coordinate. Database administrators can manage backups, permissions, and software updates within a more unified structure.

Distributed environments introduce additional responsibilities, including node monitoring, replication management, network configuration, and failure recovery.

Managed cloud services can reduce these responsibilities, but they do not eliminate architectural complexity.

What Changes When Availability and Consistency Matter?

Centralized systems can provide strong transactional consistency, although their availability depends on redundancy and failover arrangements.

Distributed systems may improve fault tolerance through replication. However, consistency depends on the technology and configuration.

AWS documentation explains that distributed architectures must address trade-offs involving consistency, availability, and network partitions.

Some systems prioritize immediate agreement between nodes. Others allow temporary differences before records synchronize.

Comparing Infrastructure Costs

Centralized solutions may require lower initial infrastructure and administrative investment for modest workloads.

Distributed databases can introduce additional networking, storage, replication, and operational expenses. However, their scalability may justify these costs when transaction volumes grow substantially.

Actual expenses depend on deployment design, licensing, cloud pricing, and staffing requirements.

How Database Integrations Affect eCommerce Operations

Modern eCommerce platforms rarely operate independently. They exchange information with enterprise resource planning (ERP), customer relationship management (CRM), inventory, accounting, and payment systems.

For example, an online purchase may trigger several connected processes. Inventory quantities change, payment confirmation is recorded, and fulfillment information passes to warehouse software.

Adobe Commerce documentation confirms that Magento-based platforms support integrations through APIs that connect external business applications.

These connections must maintain reliable data exchanges regardless of database architecture.

A centralized system may simplify access to shared records. A distributed environment may support geographically separated applications, although synchronization requires additional coordination.

Successful integration therefore depends on accurate data mapping, clear ownership of records, and dependable error handling.

Common Database Management Risks

Both database approaches face operational risks that require ongoing attention.

Synchronization and Inconsistent Records

Distributed environments can experience replication delays or conflicting updates. Centralized systems may also develop inconsistent information when external applications exchange outdated records.

Inventory discrepancies are particularly concerning because they can result in incorrect product availability.

Migration Failures

Moving data between platforms creates risks involving missing records, incompatible formats, and incomplete relationships.

Database migrations should include validation, reconciliation, backups, and rollback procedures.

Performance and Availability Problems

Poorly optimized queries, inadequate indexing, and insufficient computing resources can slow either architecture.

PostgreSQL documentation explains how replication and standby servers can support availability. However, recovery capabilities depend on the selected configuration.

Regular monitoring and testing help organizations identify weaknesses before they disrupt transactions.

Choosing an Architecture Based on Business Requirements

Choosing the right database architecture is part of a broader technology strategy for eCommerce businesses. Companies must also consider website infrastructure, hosting requirements, security, and long-term scalability.

Even decisions about domain name extensions can influence how customers recognize and access an online store. While domain selection does not directly determine database performance, both decisions contribute to building a reliable and accessible eCommerce platform.

When Does Centralization Make Sense?

A centralized architecture often suits businesses with predictable transaction volumes, limited infrastructure budgets, and straightforward administration requirements.

It can provide sufficient performance when properly configured and supported by reliable backup procedures.

When Is Distribution Worth Considering?

Distributed systems become relevant when organizations manage geographically separated operations, substantial workloads, or demanding availability requirements.

However, businesses must evaluate whether their technical teams can manage the additional complexity.

The AWS Well-Architected Framework recommends selecting database solutions according to workload needs, including consistency, latency, availability, and scalability.

A hybrid approach may also be appropriate. For example, businesses can retain a primary transactional database while using replicas or separate systems for reporting and regional workloads.

Conclusion

Centralized and distributed databases address different operational priorities. Centralized systems emphasize simpler management and controlled information handling, while distributed systems offer flexibility for demanding workloads and geographic expansion.

Neither approach is universally superior. The appropriate architecture depends on transaction requirements, infrastructure costs, technical expertise, and expected business growth. Regular performance reviews can help eCommerce businesses adapt their database strategies as operational demands change.
6 Data Processing Challenges That Affect Database Accuracy and Performance

Database Accuracy and Data Quality Management

Database software helps organizations store, organize, and retrieve information needed for daily operations. From customer records to financial transactions, databases support reporting, communication, and business decisions. However, maintaining reliable records becomes more difficult as companies collect information from digital forms, scanned documents, spreadsheets, and external applications. Each source may introduce errors, inconsistent formats, or incomplete details that affect database accuracy.

Managing these challenges requires organized data processing procedures. Some businesses use automated validation tools, while others maintain internal teams responsible for reviewing records. Organizations may also outsource data processing to handle repetitive tasks such as document extraction, conversion, and database preparation. Regardless of the approach, consistent quality controls remain essential. The following six challenges explain where problems develop and how organizations can address them.

1. Duplicate Records Create Confusion and Unnecessary Storage

Duplicate records occur when the same information appears multiple times within a database. They often result from repeated form submissions, software migrations, or separate departments entering identical customer details.

These records increase storage requirements and can distort reports. For example, a customer appearing three times in a database might be counted as three separate individuals. Duplicate entries can also cause conflicting updates when employees modify different versions of the same record.

IBM identifies uniqueness as a fundamental dimension of data quality, emphasizing that duplicate records can reduce reporting reliability.

How to Address Duplicate Data

Organizations can use automated matching tools to identify records sharing similar names, identification numbers, or contact information. Unique database identifiers help prevent repeated entries. Regular database audits also allow teams to review potential duplicates before merging or deleting records.

2. Inconsistent Data Formats Complicate Database Integration

Information collected from different applications rarely follows identical formatting rules. One system might record dates as MM/DD/YYYY, while another uses DD/MM/YYYY. Addresses may contain different abbreviations, and numerical values may use inconsistent decimal separators.

These differences become problematic when databases exchange information. Software may interpret values incorrectly, reject imported records, or produce inaccurate comparisons.

The Data Management Association (DAMA International) recognizes consistency and validity among the core dimensions of data quality, as documented by IBM.

Practical Formatting Solutions

Standardized database structures help maintain consistency. Organizations should establish common rules for dates, currencies, addresses, and numerical fields. Automated transformation tools can convert incoming information into approved formats before database insertion.

Validation rules should also detect unusual values and prevent incompatible records from entering production systems.

3. Incomplete Information Reduces Reporting Accuracy

Missing information presents another common database challenge. Customer profiles may lack contact details, transaction records may contain empty fields, or imported documents may omit required identifiers.

Incomplete records can affect calculations, reporting, and decision-making. For example, sales reports based on missing transaction information may underestimate actual activity. Database relationships can also become unreliable when essential reference fields are absent.

IBM explains that completeness measures whether the information required for a particular purpose is available. Missing values can weaken analytical results, especially when the unavailable information affects important calculations.

Improving Data Completeness

Required fields should be identified during database design. Digital forms can prevent submissions when essential information is missing.

Automated checks can flag incomplete imports for review. Organizations should also distinguish genuinely unavailable information from accidental omissions rather than filling empty fields with unsupported assumptions.

4. Manual Data Entry Errors Affect Record Accuracy

Manual data entry remains necessary when organizations process handwritten forms, scanned documents, or information unavailable through direct system integration.

However, transcription mistakes can introduce incorrect numbers, misspelled names, and misplaced decimal points. A single incorrect product code may affect inventory records, while an inaccurate invoice amount can create accounting discrepancies.

Research discussed by IBM identifies accuracy as a central measure of data quality. Incorrect information reduces the reliability of operational reports and automated decisions.

Reducing Human Errors

Organizations can combine optical character recognition with automated data validation to reduce repetitive typing. However, extracted information still requires accuracy checks, particularly when source documents contain unclear text.

Dropdown menus, predefined field formats, and verification procedures also reduce input errors. Staff training and periodic sampling provide additional quality assurance.

5. Data Integration Difficulties Disrupt Information Flow

Businesses frequently operate several software platforms, including customer relationship management systems, accounting applications, inventory databases, and legacy programs. Maintaining database accuracy and performance becomes more challenging when these systems use different data formats, structures, and processing methods.

Combining information from these systems can be difficult because their database structures, field definitions, and update schedules may differ. Integration failures can create missing records, conflicting information, or delayed synchronization.

IBM highlights consistency across systems as an important requirement for reliable data management. Without shared definitions, organizations may struggle to establish accurate records.

Building Reliable Integration Processes

Organizations should define common data structures and mapping rules before transferring information. Application programming interfaces can support structured exchanges between compatible platforms.

For older applications, extraction, transformation, and loading processes can prepare information for newer databases. Testing, error logs, and reconciliation checks help identify problems before they affect daily operations.

6. Increasing Data Volumes Strain Processing Resources

Growing organizations collect larger quantities of information through online transactions, connected applications, customer interactions, and digital documents.

Higher processing volumes can increase database workloads and delay updates. Large imports may compete with routine queries for computing resources. Processing backlogs can also leave reports dependent on outdated information.

PostgreSQL documentation explains that indexes can improve record retrieval, although excessive indexing introduces additional system overhead. Database optimization therefore requires balancing query performance with processing demands.

Managing Larger Workloads

Batch processing, automated cleaning, and scheduled imports can help distribute workloads. Organizations should monitor processing times, failed imports, storage utilization, and database response rates.

External document processing teams may provide additional capacity during unusually busy periods. Before transferring work, businesses should evaluate confidentiality requirements, access controls, compatibility with existing systems, accuracy targets, and quality assurance procedures.

Clear service requirements and regular output checks remain important whether processing occurs internally or through an external provider.

Building More Reliable Databases Through Consistent Practices

Database reliability depends on more than processing speed or software features. Duplicate records, inconsistent formats, incomplete information, manual mistakes, integration problems, and increasing workloads can all reduce data quality.

Organizations can address these challenges through standardized structures, automated validation, documented procedures, and regular monitoring. Human review remains valuable when automated systems encounter unusual or uncertain information.

As databases continue supporting increasingly complex operations, businesses will need flexible processing methods alongside dependable quality controls. Maintaining accurate information from collection through storage and retrieval provides a stronger foundation for reporting, operational efficiency, and informed decisions.