Articles

Featured

6 Data Processing Challenges That Affect Database Accuracy and Performance
Database Accuracy and Data Quality Management

Database software helps organizations store, organize, and retrieve information needed for daily operations. From customer records to financial transactions, databases support reporting, communication, and business decisions. However, maintaining reliable records becomes more difficult as companies collect information from digital forms, scanned documents, spreadsheets, and external applications. Each source may introduce errors, inconsistent formats, or incomplete details that affect database accuracy.

Managing these challenges requires organized data processing procedures. Some businesses use automated validation tools, while others maintain internal teams responsible for reviewing records. Organizations may also outsource data processing to handle repetitive tasks such as document extraction, conversion, and database preparation. Regardless of the approach, consistent quality controls remain essential. The following six challenges explain where problems develop and how organizations can address them.

1. Duplicate Records Create Confusion and Unnecessary Storage

Duplicate records occur when the same information appears multiple times within a database. They often result from repeated form submissions, software migrations, or separate departments entering identical customer details.

These records increase storage requirements and can distort reports. For example, a customer appearing three times in a database might be counted as three separate individuals. Duplicate entries can also cause conflicting updates when employees modify different versions of the same record.

IBM identifies uniqueness as a fundamental dimension of data quality, emphasizing that duplicate records can reduce reporting reliability.

How to Address Duplicate Data

Organizations can use automated matching tools to identify records sharing similar names, identification numbers, or contact information. Unique database identifiers help prevent repeated entries. Regular database audits also allow teams to review potential duplicates before merging or deleting records.

2. Inconsistent Data Formats Complicate Database Integration

Information collected from different applications rarely follows identical formatting rules. One system might record dates as MM/DD/YYYY, while another uses DD/MM/YYYY. Addresses may contain different abbreviations, and numerical values may use inconsistent decimal separators.

These differences become problematic when databases exchange information. Software may interpret values incorrectly, reject imported records, or produce inaccurate comparisons.

The Data Management Association (DAMA International) recognizes consistency and validity among the core dimensions of data quality, as documented by IBM.

Practical Formatting Solutions

Standardized database structures help maintain consistency. Organizations should establish common rules for dates, currencies, addresses, and numerical fields. Automated transformation tools can convert incoming information into approved formats before database insertion.

Validation rules should also detect unusual values and prevent incompatible records from entering production systems.

3. Incomplete Information Reduces Reporting Accuracy

Missing information presents another common database challenge. Customer profiles may lack contact details, transaction records may contain empty fields, or imported documents may omit required identifiers.

Incomplete records can affect calculations, reporting, and decision-making. For example, sales reports based on missing transaction information may underestimate actual activity. Database relationships can also become unreliable when essential reference fields are absent.

IBM explains that completeness measures whether the information required for a particular purpose is available. Missing values can weaken analytical results, especially when the unavailable information affects important calculations.

Improving Data Completeness

Required fields should be identified during database design. Digital forms can prevent submissions when essential information is missing.

Automated checks can flag incomplete imports for review. Organizations should also distinguish genuinely unavailable information from accidental omissions rather than filling empty fields with unsupported assumptions.

4. Manual Data Entry Errors Affect Record Accuracy

Manual data entry remains necessary when organizations process handwritten forms, scanned documents, or information unavailable through direct system integration.

However, transcription mistakes can introduce incorrect numbers, misspelled names, and misplaced decimal points. A single incorrect product code may affect inventory records, while an inaccurate invoice amount can create accounting discrepancies.

Research discussed by IBM identifies accuracy as a central measure of data quality. Incorrect information reduces the reliability of operational reports and automated decisions.

Reducing Human Errors

Organizations can combine optical character recognition with automated data validation to reduce repetitive typing. However, extracted information still requires accuracy checks, particularly when source documents contain unclear text.

Dropdown menus, predefined field formats, and verification procedures also reduce input errors. Staff training and periodic sampling provide additional quality assurance.

5. Data Integration Difficulties Disrupt Information Flow

Businesses frequently operate several software platforms, including customer relationship management systems, accounting applications, inventory databases, and legacy programs. Maintaining database accuracy and performance becomes more challenging when these systems use different data formats, structures, and processing methods.

Combining information from these systems can be difficult because their database structures, field definitions, and update schedules may differ. Integration failures can create missing records, conflicting information, or delayed synchronization.

IBM highlights consistency across systems as an important requirement for reliable data management. Without shared definitions, organizations may struggle to establish accurate records.

Building Reliable Integration Processes

Organizations should define common data structures and mapping rules before transferring information. Application programming interfaces can support structured exchanges between compatible platforms.

For older applications, extraction, transformation, and loading processes can prepare information for newer databases. Testing, error logs, and reconciliation checks help identify problems before they affect daily operations.

6. Increasing Data Volumes Strain Processing Resources

Growing organizations collect larger quantities of information through online transactions, connected applications, customer interactions, and digital documents.

Higher processing volumes can increase database workloads and delay updates. Large imports may compete with routine queries for computing resources. Processing backlogs can also leave reports dependent on outdated information.

PostgreSQL documentation explains that indexes can improve record retrieval, although excessive indexing introduces additional system overhead. Database optimization therefore requires balancing query performance with processing demands.

Managing Larger Workloads

Batch processing, automated cleaning, and scheduled imports can help distribute workloads. Organizations should monitor processing times, failed imports, storage utilization, and database response rates.

External document processing teams may provide additional capacity during unusually busy periods. Before transferring work, businesses should evaluate confidentiality requirements, access controls, compatibility with existing systems, accuracy targets, and quality assurance procedures.

Clear service requirements and regular output checks remain important whether processing occurs internally or through an external provider.

Building More Reliable Databases Through Consistent Practices

Database reliability depends on more than processing speed or software features. Duplicate records, inconsistent formats, incomplete information, manual mistakes, integration problems, and increasing workloads can all reduce data quality.

Organizations can address these challenges through standardized structures, automated validation, documented procedures, and regular monitoring. Human review remains valuable when automated systems encounter unusual or uncertain information.

As databases continue supporting increasingly complex operations, businesses will need flexible processing methods alongside dependable quality controls. Maintaining accurate information from collection through storage and retrieval provides a stronger foundation for reporting, operational efficiency, and informed decisions.
Featured

How Database Management Systems Keep Large Web Directories Organized and Searchable

online resource directory

Large web directories can contain thousands of website addresses, descriptions, categories, keywords, and update records. As those collections grow, basic lists become difficult to maintain. Duplicate entries can appear, links can stop working, categories can become inconsistent, and searches can return too many irrelevant results. Database management systems help solve these problems by storing directory information in structured records that can be searched, updated, validated, and connected efficiently.

A directory may store each website as a separate record containing its URL, title, description, category, keywords, verification date, and other metadata. Juso On-gil (주소온길 온라인 자료 가이드), an online directory platform in Korea, shows how website resources can be organized and presented in a structured way. Its visible layout does not reveal the specific database technology used behind the platform, but it does illustrate why consistent records are important when large collections of online resources need to be categorized, maintained, and retrieved efficiently.

Why Large Link Collections Become Difficult to Manage

A simple spreadsheet or flat file may work for a small directory. Problems appear as the collection expands. The same website might be entered twice under slightly different URLs. An operator may change a description without updating related categories. Some websites may move to new addresses while old records remain active.

A database reduces this disorder by dividing information into predictable fields. One field might hold the URL, another the category, and another the date the link was last checked. Relationships can also connect one website with several topics without requiring operators to create a completely separate record for each category.

Database constraints provide another layer of control. Documentation from MySQL explains that unique indexes can prevent duplicate values in fields where each value is expected to be distinct. This can help directory operators prevent accidental duplication when a normalized URL or another unique identifier is used as a record key.

How Indexing Makes Directory Search Faster

Storing records is only part of the problem. Users must also be able to retrieve them quickly. Searching every record one by one becomes increasingly inefficient as a database grows.

PostgreSQL documentation explains that database indexes allow a server to locate selected rows without scanning an entire table. An index works somewhat like the index of a book. Instead of reading every page to find one topic, the system uses an organized reference that points toward relevant information.

This is useful for directory searches involving categories, dates, website names, or frequently used filters. Different index types can support different search patterns. PostgreSQL, for example, provides B-tree, hash, GIN, GiST, BRIN, and other indexing methods. The best option depends on the type of data and the queries being performed.

What Happens When Users Search by Keyword?

Directory visitors often remember a topic rather than the exact name of a website. That makes keyword indexing important. A directory might associate terms such as maps, education, documents, finance, or travel with individual resource records.

Full-text indexing can make this type of retrieval more practical. PostgreSQL describes its GIN index as a generalized inverted index designed for cases where searches need to locate individual values, such as words, within larger collections of information. This approach can help systems connect search terms with matching records efficiently.

Good search design still requires careful metadata. A fast database cannot compensate for vague descriptions or badly assigned categories. Operators need clear naming rules and consistent keywords so that indexed information accurately reflects each resource.

How Filtering and Categories Improve Retrieval

Categories add another layer of organization. Rather than searching one enormous pool of links, users can narrow results by subject, purpose, date, or another useful attribute.

The public Juso-ongil guide, for example, tells visitors they can search by a known site name or by a needed function. It also presents resources through multiple subject categories and distinguishes information-check dates from registration dates. These visible features demonstrate how structured metadata can make a directory easier to browse, although they do not establish which database architecture the site uses.

From a database perspective, categories can be stored in separate tables and connected to website records through relationships. This approach can make maintenance easier because a category name can be updated centrally instead of being rewritten across many unrelated records.

Duplicate Detection Is More Than Matching URLs

Finding duplicates can be surprisingly complex. Two URLs may point to the same website even when their text is slightly different. One might use HTTP while another uses HTTPS. Tracking parameters, trailing slashes, redirects, and alternate subdomains can create additional variations.

Database rules can stop exact duplicates, while application-level processes can normalize addresses before they are stored. Operators may also compare domain names, titles, or canonical addresses to identify records that require review.

Unique constraints are particularly useful after normalization. MySQL documentation notes that a UNIQUE index rejects a new key when the same indexed value already exists. Used carefully, this prevents some forms of duplication before they enter the directory.

Why Link-Status Monitoring Matters

Directory records also age. Websites disappear, pages move, and servers return errors. Automated maintenance tools can periodically request stored URLs and record the resulting HTTP status.

RFC Editor documentation for HTTP Semantics defines status classes such as successful 2xx responses, 3xx redirects, 4xx client errors, and 5xx server errors. It also defines 301 as a permanent redirect, 404 as a missing resource, and 410 as a resource known to be gone. These signals can help directory operators identify records that should be updated, redirected, rechecked, or removed.

Automation should still allow human review. A temporary server problem does not necessarily mean a website should disappear from a directory. Recording the response, check date, and previous status creates a more useful maintenance history.

What Makes a Directory Database Scalable?

Scalability depends on more than adding storage. Database design determines how efficiently information can be validated, searched, and changed as the collection expands. Clear schemas reduce inconsistent records, while appropriate indexes improve retrieval. Related discussions of database documentation and technical workflows also show how enterprise database environments increasingly connect performance, integration, security, and maintenance processes. Validation rules can then limit avoidable errors, while automated checks help identify outdated information.

There is also a trade-off. PostgreSQL notes that indexes speed many retrieval operations but add database overhead. Directory operators therefore need to index fields that support real search and filtering needs rather than indexing everything automatically.

Accurate Data Still Matters More Than Database Size

A large directory becomes useful when its records remain understandable, current, and easy to retrieve. Database management systems provide the structure needed to store URLs, organize metadata, build category relationships, detect duplicates, support keyword searches, and record link checks.

The technology does not remove the need for careful editorial decisions. Operators still need sensible categories, clear descriptions, reliable validation rules, and realistic maintenance schedules. As directories grow, combining those practices with scalable database design can keep large resource collections searchable without allowing their underlying data to become increasingly difficult to manage.

Featured

Buy Boosting Highlights How Database Software Powers Real Time Service Platforms

Male engineer monitors real-time systems with calm focus in bright workspace.

When you buy boosting, it appears to customers as a simple, fast, and user-friendly digital service, but there is far more complexity beneath the surface.

While users appreciate speed and convenience, the underlying software that manages databases, organizes requests, keeps updates current, and ensures workflows run smoothly is often overlooked.

The Hidden Structure Behind Fast Service

Real-time services depend on much more than good design. More than anything, they depend on timing. When a customer places an order and selects a service along with specific preferences, they expect the system to respond almost instantly.

For that to happen, a significant amount of behind-the-scenes data processing and coordination must take place. For that reason, database software is more critical than most people realize.

A developer I once worked with put it simply: “People think the magic is on the front end, but the real stress lives in the records.” It sounded amusing at the time, but there’s truth in it.

The front end may look smooth and polished, but behind the scenes, multiple processes run in parallel, handling assignment management, session logs, customer notes, status updates, and even resolving timing conflicts.

When systems are well built, the user experience feels effortless. When they’re not, the cracks show quickly.

Why Accuracy Feels Like Trust

People using digital services need to trust the platform.

They may not understand how it’s built using tables, queries, indexing, and records, but they notice when the system remembers their preferences, when updates arrive on time, and when support teams already understand their concerns.

That kind of experience doesn’t happen by accident.

For platforms operating in real time, consistent data flow becomes part of the service itself. It reduces duplication, minimizes confusion, and allows teams to operate with confidence instead of guesswork.

In many cases, order management systems do more than just handle transactions. They act as the memory of the platform.

As platforms grow, that memory becomes even more important. Smaller services can get by with manual fixes for a while, but growth eventually exposes the limits of that approach.

At scale, speed without structure starts to resemble chaos, even if everything looks fine on the surface.

The Real Platform Story

There’s a certain kind of optimism in how modern systems are evolving. Improved database infrastructure doesn’t just increase speed, it makes services more responsive to real customer needs.

Workloads can be balanced more effectively, histories are preserved, progress is tracked accurately, and potential issues can be addressed before they turn into complaints.

This shift changes how companies operate.

Instead of constantly reacting to problems, teams can act ahead of them. Rather than digging through scattered notes, service teams can clearly see what’s happening and step in before issues escalate.

The strongest platforms are beginning to recognize that system stability itself is a competitive advantage, alongside resilience, precision, and strong database security.

Featured

The Rising Influence of SEO Tools on Modern Database Engineering Practices

Two engineers collaborate in a bright office with blurred laptop screens visible.

The digital world has evolved in a way that marketers and engineers no longer operate in separate silos. One of the most surprising intersections of both fields is the group plan model for SEO tools, which is grabbing the attention of database specialists.

Through collective pooling of resources, businesses are able to affordably access powerful SEO analytics and, at the same time, are finding novel ways to incorporate this data into their database workflows.

Why database engineers are paying attention

The discipline of database engineering has always emphasized performance, scalability, and reliability. Faced with the inflow of search data, this focus has had to shift to accommodate attaining volumes of keyword reports, backlink analyses, and traffic metrics.

Collaborative plans enable engineering teams to access SEO tools, which generate valuable data streams for legacy systems. This shift is the reason why discussions about SEO tools are no longer the sole purview of marketing teams.

Cost efficiency and data accessibility

From an engineering perspective, the broader cost-sharing approach provides data insights that were previously available at a high premium to research groups and startups.

Such smaller organizations often find the advanced features of SEO software prohibitively expensive. The pooled cost approach makes essential insights and analyses of data features affordable.

Engineers can experiment and innovate with SEO integrated and processed data, as well as business core databases, thanks to this wider access.


ALSO READ: Smart Branding, Smart Tech: How Database Startups Use AI Headshots to Build Trust with Investors and Clients


Enhancing analytics and reporting systems

Dashboards created to show and visually explain the connections between what customers do, business results, and search visibility are meant to be useful when the SEO data is organized and saved correctly.

Only after the data is properly indexed and stored can it be released to drive predictive analytic models, generating valuable insights for the company.

Analytics and reporting systems are progressively emphasizing the integration of operational and marketing data. The ASC conversation is therefore not only about cost saving but also about analytic value generation.

Cooperation beyond borders

New shared access plans are fostering a new form of collaboration between database teams and the marketing department.

Engineers have the chance to appreciate the usefulness of the keyword performance metrics, while marketers acquire a better understanding of the workings of a data pipeline.

This partnership fosters the development of mechanisms that not only archive SEO data but also utilize it to enhance crucial business strategies. Increasingly, companies view the SEO tools group plan as a collaborative effort.

Constraining the willingness to innovate

Even though it is hardly debatable, the benefits noted are clear to everyone; some engineers point out the possible drawbacks.

Even when shared plans are available, they may impose certain limitations on the number of features, and questions arise about the extensibility of data exports and the reliability over time for any given provider.

Still, the increasing interest from engineering circles indicates that these problems are not sufficiently serious to overshadow the benefits.

Firms are more inclined to engage in exploratory activities when the exploration cost is a fraction of the price of buying an individual subscription.

The constant change in technology is a rapidly emerging movement within technical communities, which was previously regarded as merely a side hobby.

Discussing the use of the database as an SEO tool is common even among database engineers focusing on the server side. This phenomenon is an indicator of a more significant trend: the marketing and engineering disciplines are no longer strictly separate.

The discourse is only going to increase as more companies look for more sophisticated and data-centric strategies.

Featured

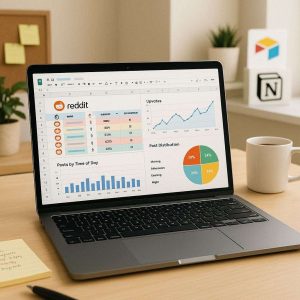
Database Software Can Help Boost Your Reddit Post Visibility

In Reddit, visibility is everything. Whether you’re promoting a product, sharing your expertise, or starting a conversation, getting noticed is a challenge. This is where smart tools, like database software, can give you a real edge to boost your Reddit post visibility.
What Is Database Software?

Database software is a tool that helps you collect, organize, and manage information. Businesses use it to store data like customer details, sales records, inventory lists, and more. But it’s not just for big companies. Anyone can use database software to track information that helps with planning and decision-making.

For Reddit, database software can be used to:

  • Track which subreddits perform well
  • Monitor the best times to post
  • Record engagement metrics
  • Analyze trends in comments or reactions

Instead of guessing what works, you’ll have data to back it up.

Why Reddit Needs Strategy

Reddit is not like Facebook or Instagram. It’s a community-driven platform with rules that vary by subreddit. To succeed, you need to understand where your audience hangs out and how they respond.

Here are some common challenges people face when trying to get attention on Reddit:

  • Choosing the wrong subreddit
  • Posting at the wrong time
  • Repeating the same mistakes
  • Ignoring engagement patterns

By using a database, you can collect information about your past Reddit posts and learn from them.

How to Use Database Software to Boost Visibility

Here’s a step-by-step guide on how to use database software effectively to improve your Reddit performance:

1. Build a Post Tracker

  • Start by creating a simple table that includes:
  • Subreddit name
  • Date and time of posting
  • Title or topic
  • Number of upvotes
  • Number of comments
  • Any useful feedback or trends

Tools like Airtable, Notion, or Google Sheets work great for this. Over time, you’ll see which combinations get the best results.

2. Analyze Best-Performing Subreddits

Not all subreddits are created equal. Some are more active, others are more niche. A database helps you spot where your content fits best.

For example, if you’re sharing tips about tech, you might find that r/technology gets fewer upvotes than r/TechTips — but r/TechTips may have a more engaged audience. Database insights help you focus on quality, not just quantity.

3. Track Posting Schedules

Timing matters. Use your database to find patterns. Maybe your posts get more attention on Tuesday mornings or late Sunday evenings. Once you find that sweet spot, stick to it.

You can also use your database to plan future posts. That way, you’re consistent — and consistency gets rewarded on Reddit.

4. Save Good Post Templates

If a certain post title format worked really well, save it. If a tone or topic sparked discussion, record that too. This way, you’re not starting from scratch each time. Your database becomes a toolkit of proven strategies.

Bonus Tips to Improve Reddit Visibility

While database software gives you structure, here are a few extra tips to boost your reach:

  • Engage with Comments: Don’t just post and leave. Join the conversation. Reddit users value interaction.
  • Follow Subreddit Rules: Every subreddit has its own do’s and don’ts. Follow them to avoid being removed.
  • Use Flair and Formatting: Use available post flairs and formatting tools to make your post stand out.
  • Keep It Relevant: Tailor each post to the specific interests of that subreddit. Avoid copy-pasting the same message across different communities.

When combined with data from your database, these actions help you fine-tune your Reddit game.

Featured

The Importance of Database in a Towing Company

The Role of Databases in Modern Towing Operations

In the towing industry, the integration and effective use of databases play a pivotal role in streamlining operations, improving efficiency, and maintaining high levels of customer satisfaction. A robust database system is fundamental to the success and scalability of a towing company, as it supports critical business functions such as dispatch management, vehicle tracking, customer relationship management, and financial operations.

Improving Dispatch Management Efficiency

Databases are essential for efficient dispatch management. A towing company such as San Jose tow service handles a high volume of service requests each day, and a well-structured database enables real-time tracking and organization of these calls. By storing detailed information for every request, such as customer details, vehicle type, location, and issue severity, dispatchers can quickly identify priorities and assign the closest available tow truck.

This streamlined process reduces response times, minimizes confusion, and ensures that resources are used efficiently. Faster dispatch decisions directly translate into improved customer satisfaction and smoother day-to-day operations.

Enhancing Vehicle Tracking and Fleet Management

Vehicle tracking is another area where databases deliver significant value. A comprehensive database allows towing companies to monitor tow truck locations, availability, and routes in real time. With this information, dispatchers can optimize routing, reduce fuel costs, and respond more effectively to urgent service calls.

In addition, databases support long-term fleet management by tracking maintenance schedules, service records, and repair histories. This proactive approach reduces unexpected breakdowns, minimizes downtime, and extends the operational lifespan of fleet vehicles.

Strengthening Customer Relationship Management

Customer relationship management (CRM) is greatly enhanced through database-driven systems. By maintaining detailed records of customer interactions, service history, and feedback, towing companies can deliver more personalized and consistent service experiences.

These insights also support targeted marketing efforts by identifying repeat customers, commercial accounts, or specific service trends. Over time, this data-driven approach helps build trust, loyalty, and long-term relationships with clients.

Supporting Accurate Financial Operations

Databases play a critical role in managing financial operations within a towing business. They enable accurate tracking of invoices, payments, operating expenses, and revenue streams. This ensures reliable financial reporting and simplifies tasks such as budgeting, forecasting, and tax preparation.

With a clear and organized financial overview, company leaders can make informed strategic decisions that support growth, efficiency, and profitability.

Conclusion: Databases as a Foundation for Growth

In summary, databases are integral to the smooth and successful operation of a towing company. They improve dispatch efficiency, enhance vehicle tracking, strengthen customer relationships, and support sound financial management. By leveraging well-designed database systems, towing companies can achieve operational excellence, deliver superior customer service, and maintain sustainable growth in an increasingly competitive industry.